 Llama Factory
Most Llama Factory problems fall into a few buckets. This list goes through each with the fix that usually works.
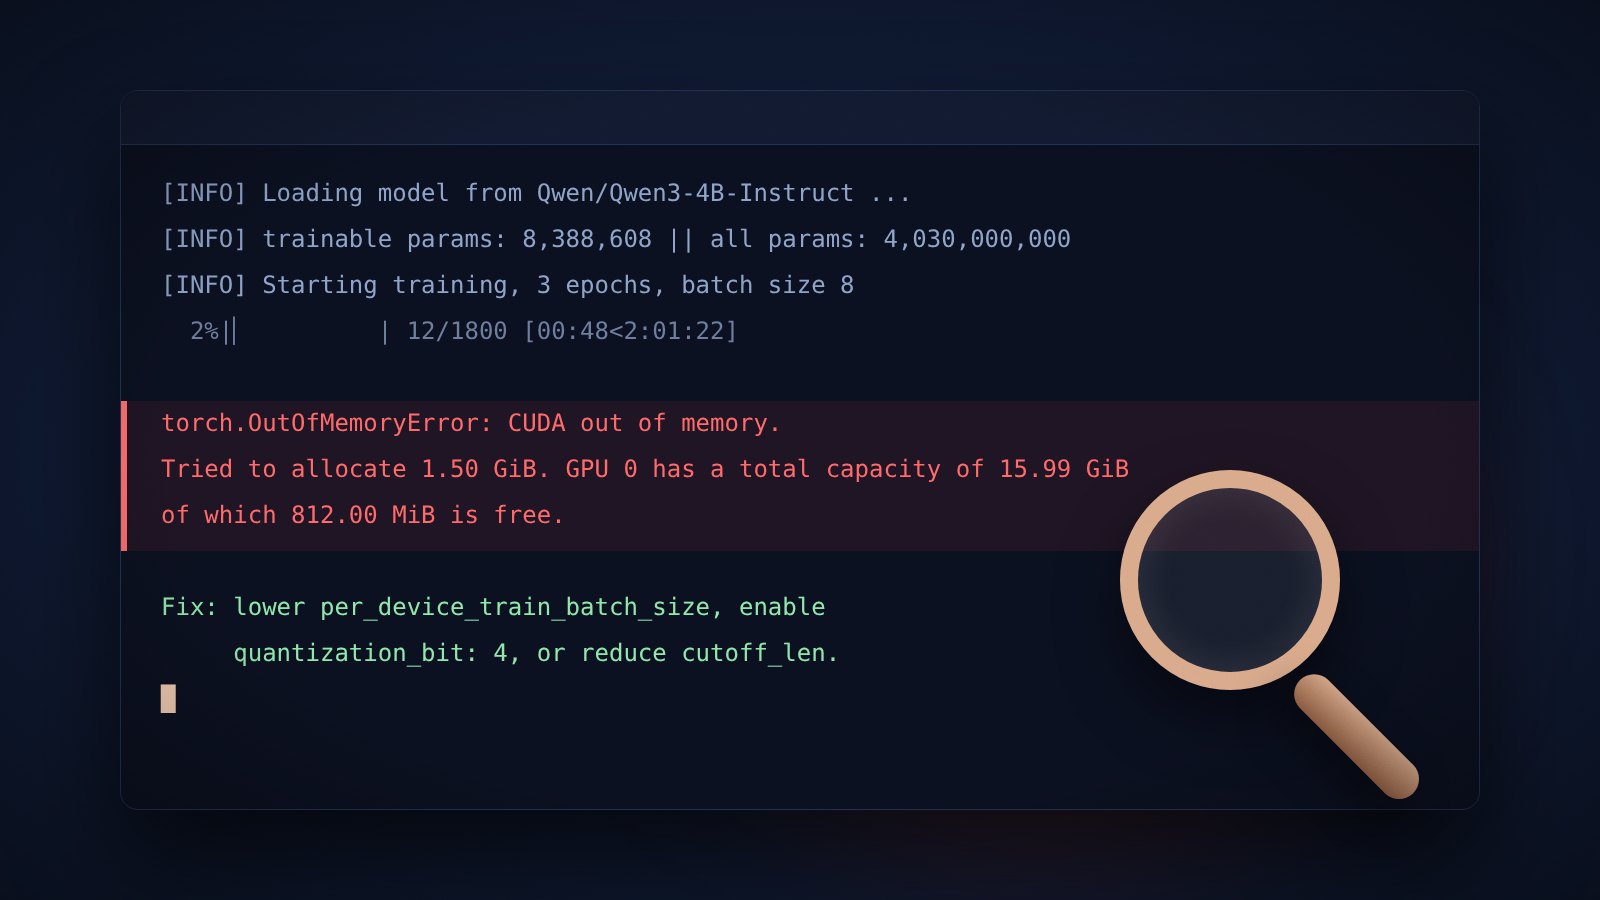
Llama Factory CUDA out of memory
The most frequent error. Try these in order:
- Set
quantization_bit: 4to switch to QLoRA. - Lower
per_device_train_batch_sizeto 1 and raisegradient_accumulation_steps. - Reduce
cutoff_lento 1024 or 512. - Enable
flash_attn: fa2on Ampere or newer cards. - Use DeepSpeed ZeRO-3 with offload on multi-GPU hosts.
Llama Factory version mismatch errors
Messages like ImportError: cannot import name ... from transformers or peft usually mean a package is older than the minimum. Reinstall with pip install -e . from the source folder, which pins compatible ranges.
Llama Factory template not found
Each model family needs the right template value (for example llama3, qwen3, gemma). The supported list is in the README model table. A wrong template trains fine but produces odd replies at inference.
Llama Factory cannot see the GPU
The CPU build of PyTorch is installed. On Windows, uninstall torch and reinstall from the CUDA index URL. On Linux, check that the driver version supports the CUDA version in the wheel.
Llama Factory can't pickle local object (Windows)
Set dataloader_num_workers: 0. Windows uses spawn for workers and some dataset functions cannot be pickled.
bitsandbytes errors in Llama Factory
On Windows, install bitsandbytes after the GPU build of PyTorch and match the CUDA Toolkit version. On NPU, bitsandbytes must be compiled from the multi-backend branch.
Llama Factory loss is NaN or does not fall
Lower the learning rate (1e-4 for LoRA, 1e-5 for full tuning are safe starts). Check the dataset preview for empty outputs. For bf16 problems on older GPUs, switch to fp16: true.
The Llama Factory web UI will not open
Port 7860 may be in use. Set GRADIO_SERVER_PORT=7861. On a remote machine, forward the port with SSH or set GRADIO_SERVER_NAME=0.0.0.0.
Still stuck with Llama Factory?
Run llamafactory-cli env and include the output when searching the project's issue tracker. Most errors already have a thread with a fix.